Achuth
Founder & CEO, OneInfer
Achuth is the founder of OneInfer. He graduated from IIT Roorkee and spent five years as a software engineer building backend infrastructure for Finweave, a US-based fintech startup. He started OneInfer to solve the cost and latency problems teams face when deploying AI models at scale.
Articles by Achuth
GPU Endpoints for RAG: Fastest Response Times at the Lowest Token Cost (2026)
Compare six GPU endpoint providers for RAG by response speed, input-token cost, prompt caching, routing, and deployment model.
August 24, 2026
Top 10 AI Inference Platforms in 2026 (Compared)
Compare ten leading AI inference platforms on latency, cost efficiency, model coverage, deployment flexibility, and production readiness.
August 24, 2026
The 5 Best AI Inference Providers in 2026
A production-focused shortlist of OneInfer, Together AI, Fireworks AI, Groq, and Baseten, with a clear explanation of who each provider fits.
August 24, 2026
Best LLM Inference API in 2026: 6 Providers Compared
An honest comparison of Together, Fireworks, Baseten, Replicate, DeepInfra, and OneInfer by speed, price, modality, and deployment.
July 24, 2026
The Llama 3.1 API for Production Inference
Call Llama 3.1 through OneInfer's OpenAI-compatible API with intelligent routing, automatic failover, and dedicated deployment options.
July 24, 2026
AI Cloud Hosting Meets Local Infrastructure: Why You Need Both
Cloud AI hosting is powerful, but the strongest AI teams are learning where local infrastructure changes the cost, privacy, and latency equation.
May 27, 2026
How OneInfer Edge Knows If Your Machine Can Run Any Hugging Face Model Before You Deploy It
Paste a model ID. OneInfer Edge scans your GPU, VRAM, OS, and installed serving libraries, then gives you a Hardware Ready verdict before deployment.
May 26, 2026
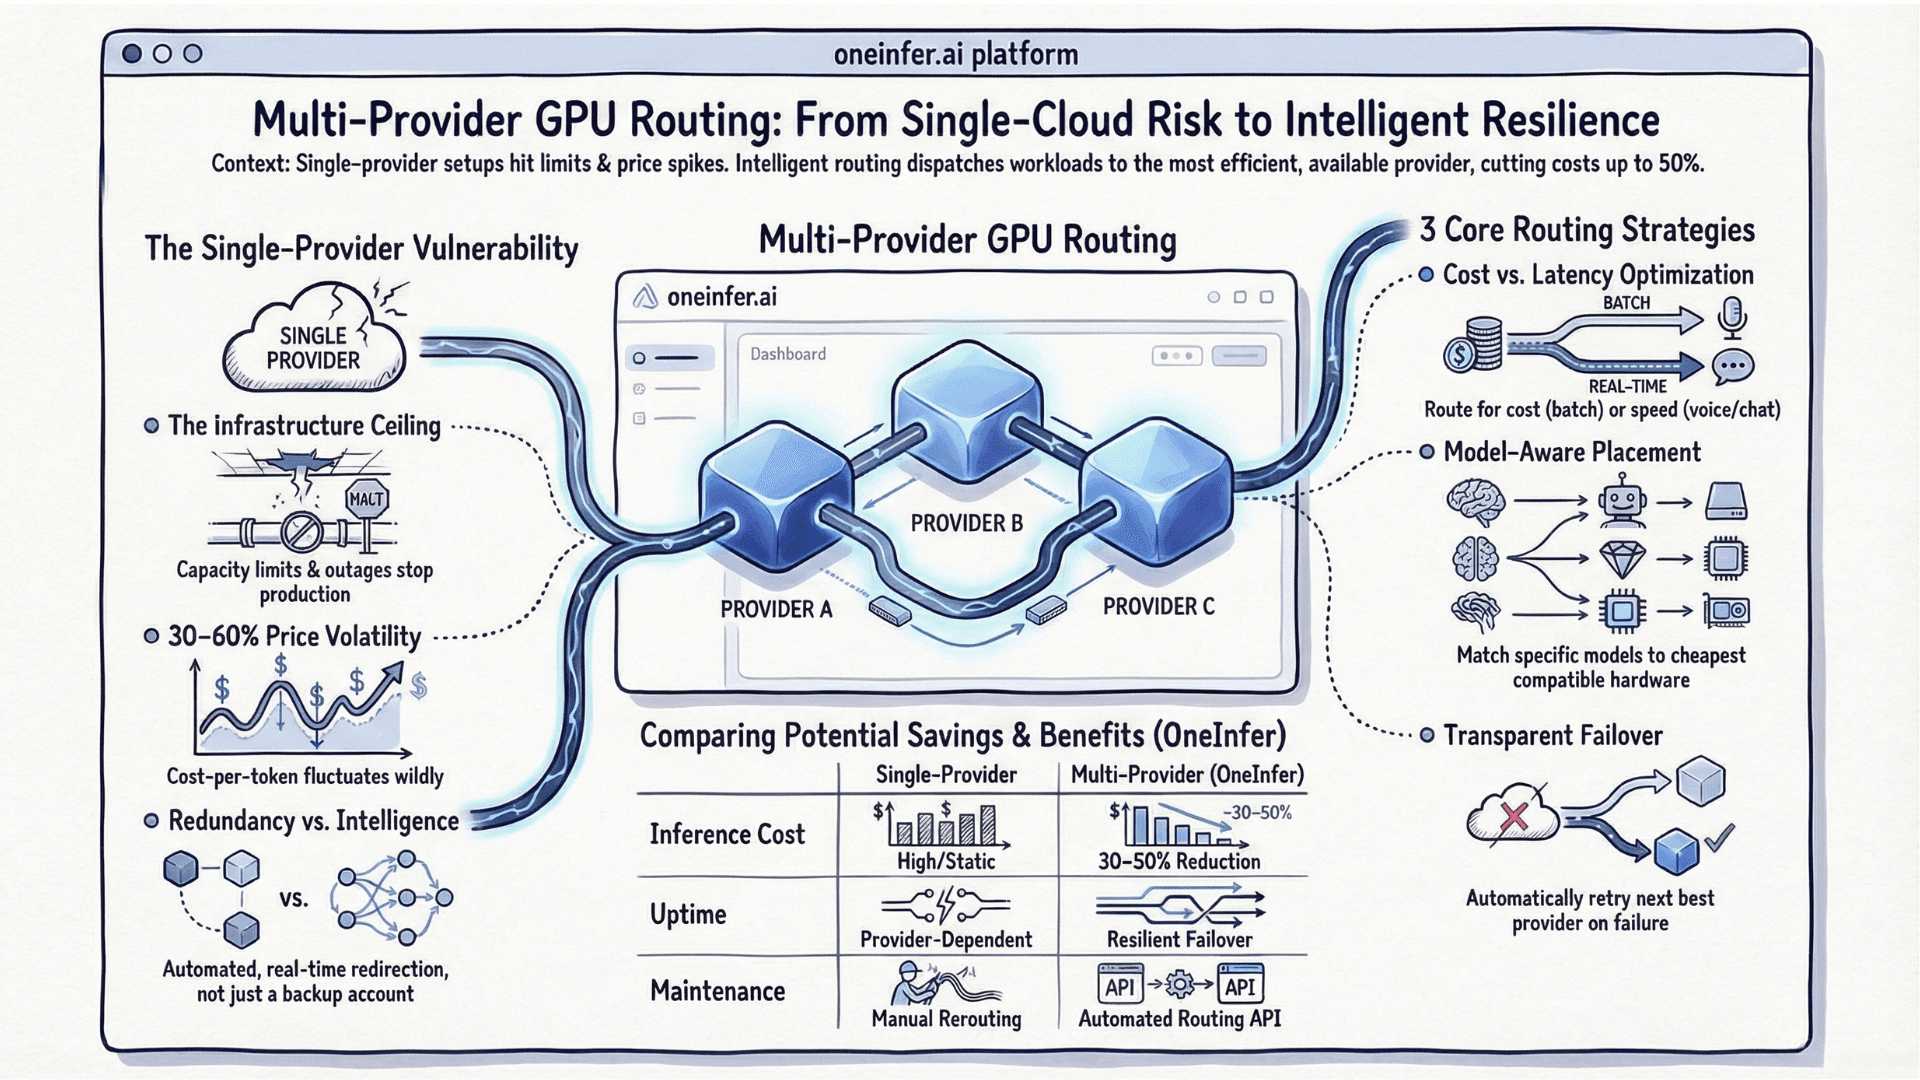
Multi-Provider GPU Routing: A Practical Guide for AI Teams
Multi-provider GPU routing sends each inference request to the best available GPU provider in real time — chosen on latency, cost and availability, with automatic failover.
July 24, 2026
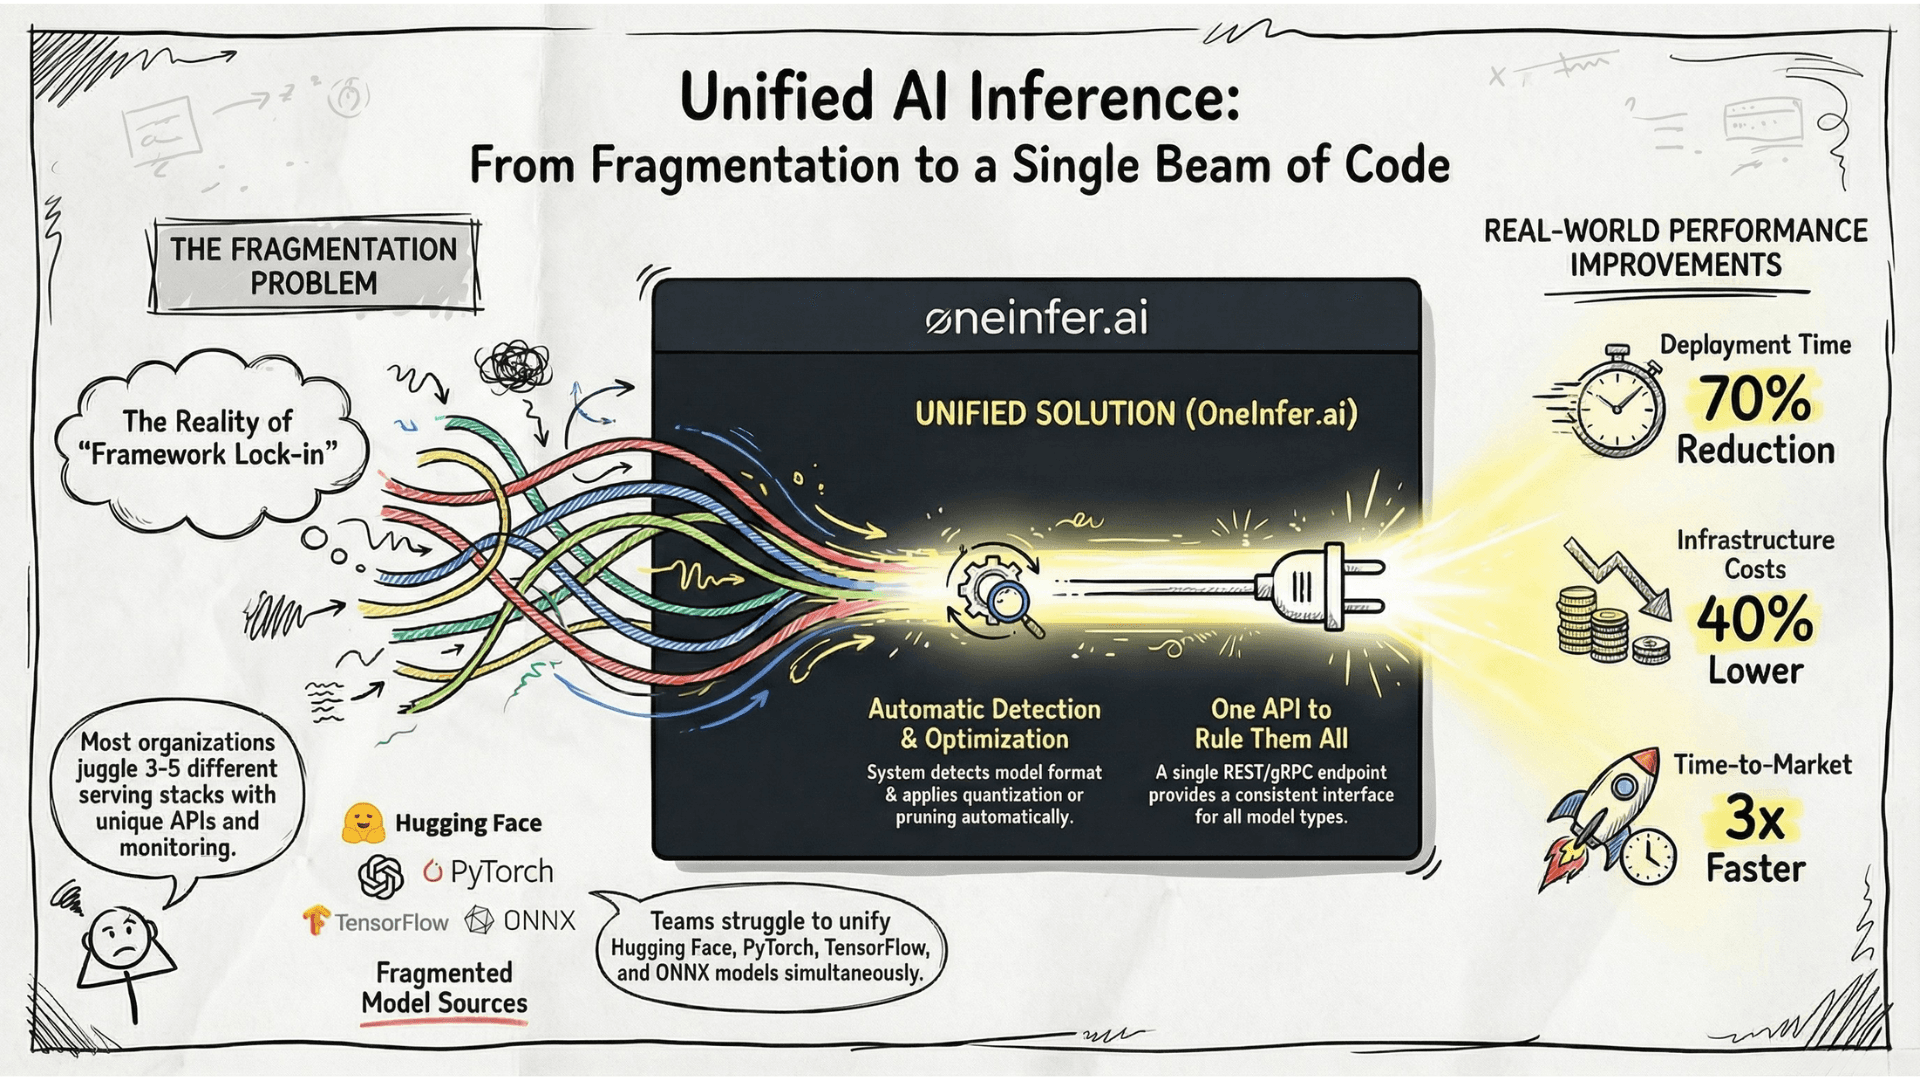
Unified AI Inference: Run Any Model With One API
Unified AI inference runs any model — text, vision, audio, video — through one OpenAI-compatible API, instead of a serving stack per model.
July 24, 2026
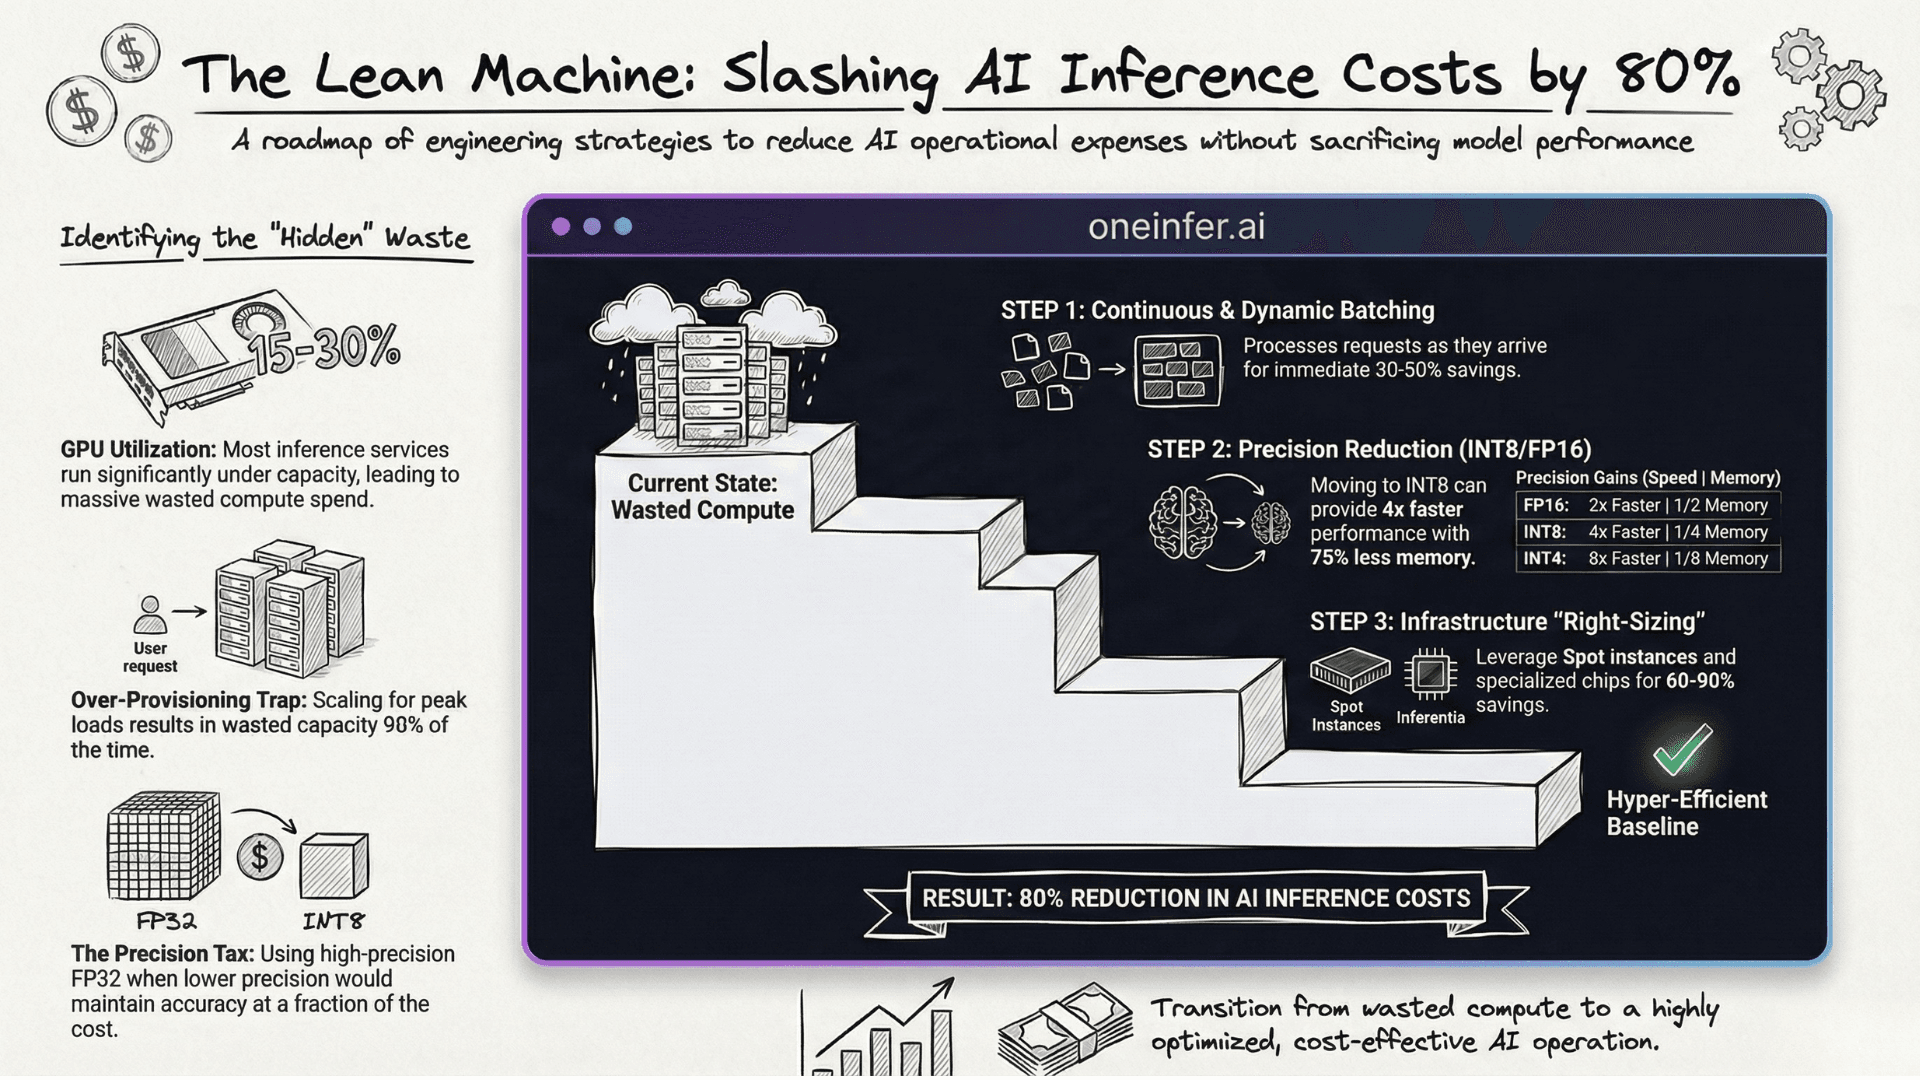
How to Reduce AI Inference Costs by 80%: Strategies That Actually Work
Reduce AI inference costs by up to 80% with six proven levers — routing, right-sizing, batching and kernel optimization. Plus the cost estimator on our pricing page.
July 24, 2026